Personal Growth
TokenPulse: Building the Leadership Team Behind Cost-Efficient AI Inference

As artificial intelligence (AI) moves from model training into large-scale production, inference computing is becoming an increasingly important factor in the economics of AI infrastructure. Inference demand is climbing alongside: the global AI infrastructure market is projected to grow from $982 billion in 2025 to $1.98 trillion by 2027, doubling in size over the two-year period. Companies deploying AI applications face rising inference costs, demanding real-time latency requirements, and the challenge of scaling their platforms as traffic grows.
In this environment, access to GPUs alone is no longer sufficient. The more difficult task is turning available computing capacity into reliable, cost-efficient token output at scale. Doing so requires not only advanced hardware and software optimization, but also the infrastructure partnerships, operational expertise, and commercial relationships needed to support growing demand.
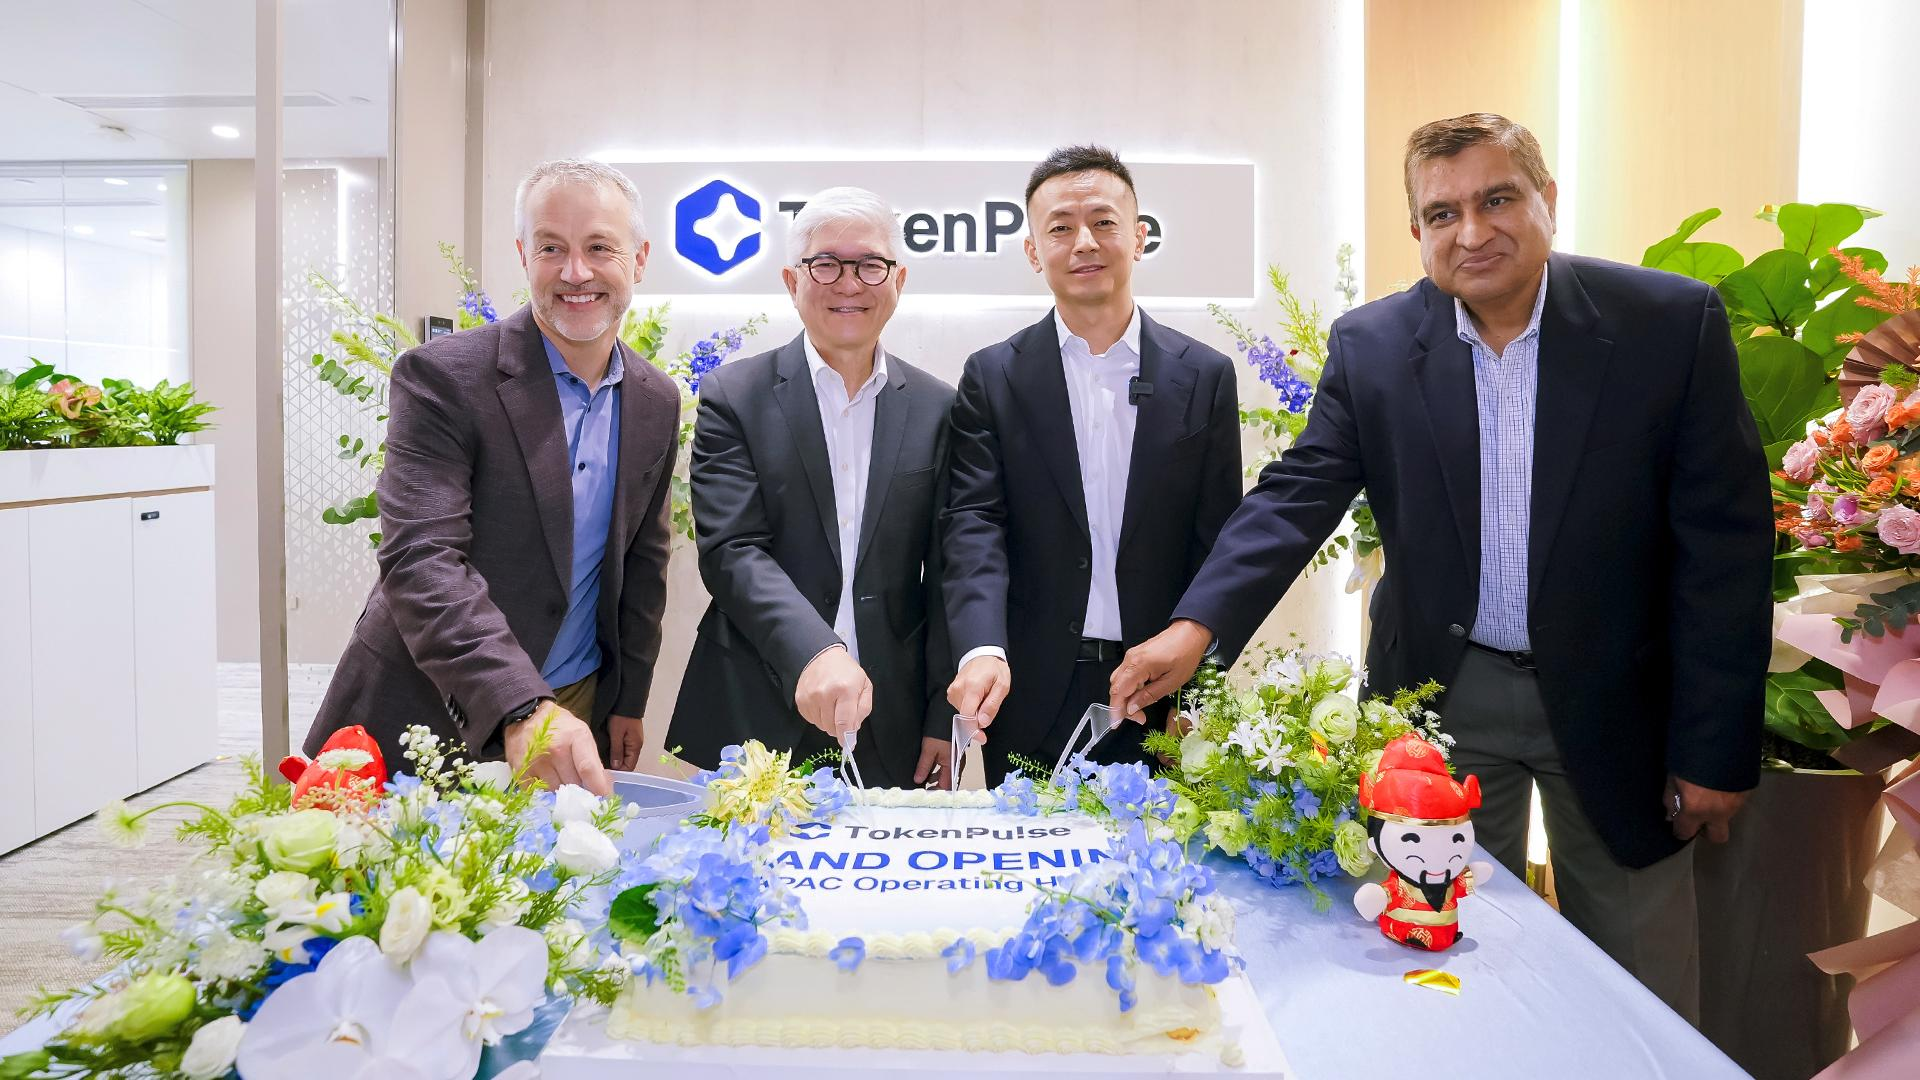
This is the challenge that TokenPulse, a next-generation AI inference infrastructure company headquartered in San Francisco and Singapore, is seeking to address. Following the opening of its Asia-Pacific Operating Hub in Singapore, the company is bringing together data-center resources, GPU infrastructure, optimized inference engines, and globally coordinated serving capabilities to support AI workloads across regions.
Beyond its technology strategy, TokenPulse is placing considerable emphasis on the leadership team responsible for putting that infrastructure into operation. With backgrounds spanning data centers, government, investment, cloud engineering, and enterprise commercialization, its executives bring different capabilities to the increasingly complex business of AI inference.
Infrastructure Leadership and Regional Delivery
At the center of TokenPulse’s infrastructure strategy is Chairman Thomas Pang, whose more than 30 years of executive experience span government, investment, infrastructure, and corporate leadership.
Pang spent over two decades with Keppel, including serving as CEO of Keppel’s Data Centres & Networks Division from 2014 to 2024. In that role, he oversaw the group’s global data-center portfolio and digital connectivity businesses, gaining experience in the infrastructure development and partnerships that underpin large-scale computing operations.
That background is particularly relevant as TokenPulse expands its presence in Southeast Asia. While GPU performance and software efficiency remain central to AI inference, the ability to secure suitable data-center capacity, coordinate regional infrastructure resources, and establish long-term partnerships can be equally important to commercial delivery.
From its Singapore operating hub, TokenPulse is developing infrastructure relationships across Malaysia, Indonesia, Thailand, and the wider region. Singapore also serves as a strategic link between North America’s AI technology and customer ecosystems and Southeast Asia’s expanding data-center and energy resources.
Pang’s experience across public-sector engagement, investment, and infrastructure development provides a foundation for navigating these regional relationships. Rather than viewing computing capacity as a standalone resource, TokenPulse’s strategy depends on coordinating infrastructure availability with the technical and commercial requirements of AI applications.
“Singapore is a natural choice for building our APAC operating hub, given its mature data center ecosystem, strong network connectivity, and deep talent pool,” said Pang. “Our foundations are rooted in decades of experience across data centers, networking, & cloud computing. Drawing on that experience in building and operating infrastructure at scale, we will continue investing in compute capacity and ecosystem support, delivering the best performance at the lowest cost per token.”
His comments reflect a broader challenge facing inference infrastructure providers: translating data-center resources into computing services that can meet the performance, cost, and reliability expectations of global AI customers.
Deep Engineering and Cloud Optimization
Securing physical infrastructure is only one part of the equation. The efficiency of the software running on that infrastructure also determines how effectively GPU capacity can be converted into useful AI output.
CTO John Liu leverages 13 years of AI/ML infrastructure and Microsoft Azure experience to lead the optimization of the company’s inference engine. His work allows enterprises to lower the costs of demanding AI models without sacrificing performance.
TokenPulse uses technologies including context parallelism and multi-tier key-value (KV) caching through HiCache to reduce repeated computation and improve serving performance.
According to the company’s reported results, its cluster-level cache hit rate can reach 95%, while context parallelism has enabled up to a 75% reduction in 99th-percentile time to first token (P99 TTFT) compared with the same workload without context parallelism enabled. Actual performance improvements vary depending on workload and operating conditions.
These engineering capabilities illustrate how inference economics depends on more than GPU specifications. Effective software optimization can help businesses extract greater value from existing computing resources, making technical expertise an important part of TokenPulse’s commercial strategy.
High-Density Compute and GPU Partnerships
Matthew Rix, Senior Vice President of AI Infrastructure and Strategic Partnerships, brings over 20 years of data-center and cloud partnerships experience to TokenPulse. Leveraging a background that includes building a $90 million of DGX SuperPod pipeline with NVIDIA, Dell and IBM, he leads TokenPulse’s AI infrastructure strategy and strategic alliances.
As AI inference workloads expand, infrastructure providers must consider not only access to advanced GPUs, but also how hardware can be deployed, supported, and scaled across different operating environments.
Rix’s background helps connect these infrastructure requirements with practical deployment planning and commercial partnerships. TokenPulse’s roadmap includes the deployment of latest-generation NVIDIA AI infrastructure as part of its broader capacity expansion strategy.
Together with Pang’s infrastructure expertise and Liu’s engineering work, this adds another layer to the company’s approach: aligning physical capacity, hardware deployment, and software efficiency rather than treating them as separate priorities.
Global Commercialization and Enterprise Expansion
Building an efficient inference platform also requires a clear understanding of how businesses intend to use it.
Senior Vice President Mazhar Hussain is a former Google executive drawing on 18 years of experience in AI and cloud, including partner ecosystem development with Microsoft, Meta, and NVIDIA, which drove over $1 billion in growth. He leverages this background to connect TokenPulse’s technical infrastructure with commercial demand from global enterprises and AI platforms.
Different customer groups have different requirements for inference capacity. Some developers need flexible access while testing applications, while established enterprise customers may require more predictable performance, dedicated infrastructure, or longer-term capacity arrangements.
Understanding these differences is an important part of translating technical capabilities into services that customers can adopt and expand over time.
Hussain’s commercial background complements the company’s engineering and infrastructure capabilities by helping connect its computing platform with the expectations of global AI customers and strategic partners.
Strategic Governance and Business Implications
CEO Steven Zhou, a serial entrepreneur with over 20 years of experience scaling businesses across the U.S. and Asia, drives TokenPulse’s overarching corporate strategy alongside CFO Mark Lu. They align capital planning and long-term investment to sustain expansion in the highly infrastructure-intensive AI industry.
Together, the leadership team’s experience supports TokenPulse’s approach to AI inference: combining infrastructure access, software optimization, hardware partnerships, and enterprise commercialization within a single business model.
That approach is reflected in the company’s flexible consumption options, built around the principle of “Start small. Scale without replatforming.”
Customers can access computing capacity through three models on a unified technology stack:
- Serverless (Pay per Token): API-based access for model evaluation, rapid deployment, and variable workloads.
- On-Demand (Pay per GPU-Hour): Dedicated computing resources for customers requiring greater control and predictable performance.
- Reserved Capacity: Contracted infrastructure capacity for sustained workloads and more customized requirements.
TokenPulse also offers managed cloud, Private VPC, and Bring Your Own Cloud (BYOC) deployment options to accommodate different operational and infrastructure needs.
The intention is to allow customers to begin with smaller AI workloads and expand their computing requirements without having to rebuild their platforms as their applications grow.
For businesses evaluating inference providers, that flexibility can matter as much as raw computing performance. Infrastructure availability, cost efficiency, deployment options, and the ability to support long-term growth all influence whether AI applications can scale successfully.
TokenPulse’s strategy brings these considerations together, with its multidisciplinary leadership team providing the experience needed to address challenges at different stages of the infrastructure value chain.
As competition in AI inference increasingly shifts from GPU ownership toward efficient and reliable token delivery, the ability to coordinate technology, infrastructure, partnerships, and commercial execution may become an important differentiator.
For TokenPulse, the opening of its Singapore hub represents one part of that broader effort. Its longer-term challenge will be turning the combined expertise of its leadership team into scalable inference services that can meet the evolving demands of the global AI market.
About TokenPulse
TokenPulse is a next-generation AI inference infrastructure company headquartered in San Francisco and Singapore. The company combines latest-generation GPU infrastructure, an optimized inference engine, and global AI infrastructure capabilities to deliver high-performance, cost-efficient compute for foundation model companies, AI platforms, enterprises, and AI-native applications worldwide.
Learn more: www.tokenpulse.com


-

 Resources5 years ago
Why Companies Must Adopt Digital Documents
-

 Resources4 years ago
A Guide to Pickleball: The Latest, Greatest Sport You Might Not Know, But Should!
-

 Resources1 year ago
50 Best AI Free Tools in 2025 (Tried & Tested)
-

 Resources1 year ago
Get Paid $5000+ a month to write : Discover 30 Spectacular Websites That Reward Your Writing Effort